[最も共有された! √] python 标准化 standardscaler 896393-Python标准化standardscaler
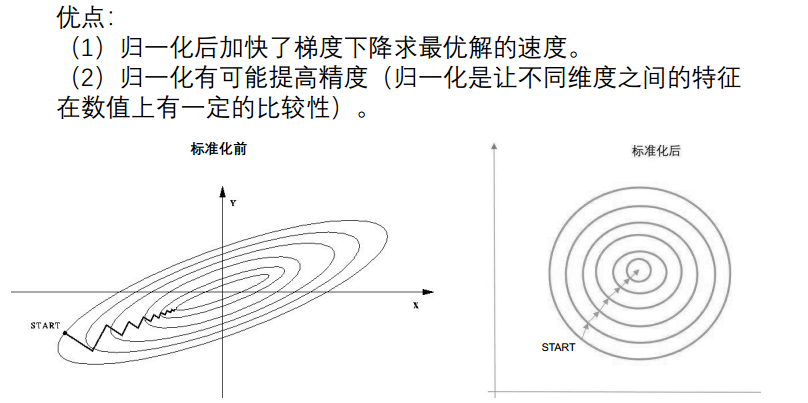
一、数据标准化 / 归一化的作用提升模型精度:标准化 / 归一化使不同维度的特征在数值上更具比较性,提高分类器的准确性。提升收敛速度:对于线性模型,数据归一化使梯度下降过程更加平缓,更易正确的收敛到最优解。二、标准差标准化 StandardScalerfrom sklearnpreprocessing import StandardScaler使用均值書籍 Python機械学習プログラミング 達人データサイエンティストによる理論と実践 の中に、特徴量の尺度の話がでてきました。 特徴量の尺度を揃えなさい、揃え方には正規化と標準化があり、多くの機械学習アルゴリズムでは標準化が実用的、といった内容でした。 StandardScalerを試してみる Python MachineLearning sklearn sklearnpreprocessingStandardScaler について簡単に調べたのでメモとして残します。 StandardScaler はデータセットの標準化機能を提供してくれています。 標準化を行うことによって、特徴量の比率を揃えることが

Python Scikit Learn 数据的预处理 标准化 Standardscaler Houyanhua1的博客 Csdn博客 Python Standardscaler
Python标准化standardscaler
Python标准化standardscaler-归一化和标准化的对比分析: 首先明确,在机器学习中,标准化是更常用的手段,归一化的应用场景是有限的。 我总结原因有两点: 1、标准化更好保持了样本间距。 当样本中有异常点时, 归一化有可能将正常的样本"挤"到一起去。比如三个样本,某个Python StandardScaler 30 examples found These are the top rated real world Python examples of sklearnpreprocessingStandardScaler extracted from open source projects You can rate examples to help us improve the quality of examples def check_transformer_pickle (name, Transformer) X, y = make_blobs (n_samples=30, centers= 0, 0, 0, 1, 1


机器学习基础一文带你用做特征工程 新闻时间
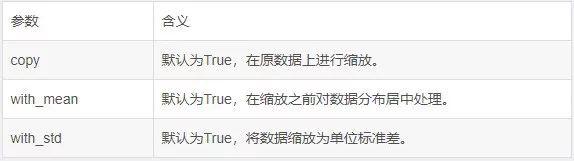
方法一: 使用 sklearn 包来实现归一化: from sklearn preprocessing import MinMaxScaler preprocess = MinMaxScaler() raw_data = 10, 10, 100, 1000, 5, 1, 21, 5, 1, 2, 15, 1 data = preprocessfit_transform( raw_data) 会输出 array 数据格式,可以看到最后一列中的 1000 由于数据值太大,导致 5 相对其With_mean;with_std 默认的值都是True copy 如果为false,就会用归一化的值替代原来的值;如果被标准化的数据不是nparray或scipysparse CSR matrix, 原来的数据还是被copy而不是 Python中preprocessingStandardScaler ()在线标准化方法案例 import numpy as np from sklearn import preprocessing import utils data = utilsreadData () data0 = npasarray ( datailoc , 2)reshape (1, 1) data1 = npasarray ( datailoc , 2)reshape (1, 1) data2 = npasarray ( datailoc , 2)reshape (1, 1) scaler1 = preprocessing
zscore 标准化 这种方法基于原始数据的均值 (mean)和标准差 (standard deviation)进行数据的标准化。 将A的原始值x使用zscore标准化到x'。 zscore标准化方法适用于属性A的最大值和最小值未知的情况,或有超出取值范围的离群数据的情况。 将数据按其属性 (按列进行 scaler = StandardScaler()fit(featuresvalues) features = scalertransform(featuresvalues) scaled_features = pdDataFrame(features, columns = col_names) Name Age Weight 0 1 2 I accidentally deleted the /usr/bin/python directory and now i am unableRun 8686s history 1 of 1 Cell link copied License This Notebook has been released under the Apache open source license
The idea behind StandardScaler is that it will transform your data such that its distribution will have a mean value 0 and standard deviation of 1 In case of multivariate data, this is done featurewise (in other words independently for each column of the data) Given the distribution of the data, each value in the dataset will have the mean value subtracted, and thenThe following are 30 code examples for showing how to use sklearnpreprocessingStandardScaler()These examples are extracted from open source projects You can vote up the ones you like or vote down the ones you don't like, and go to the original project or source file by following the links above each example 2 This question does not show any research effort;

Python在机器学习中的使用之一 数据预处理 1宝金博官网送3彩金可以提现吗 金宝博链接
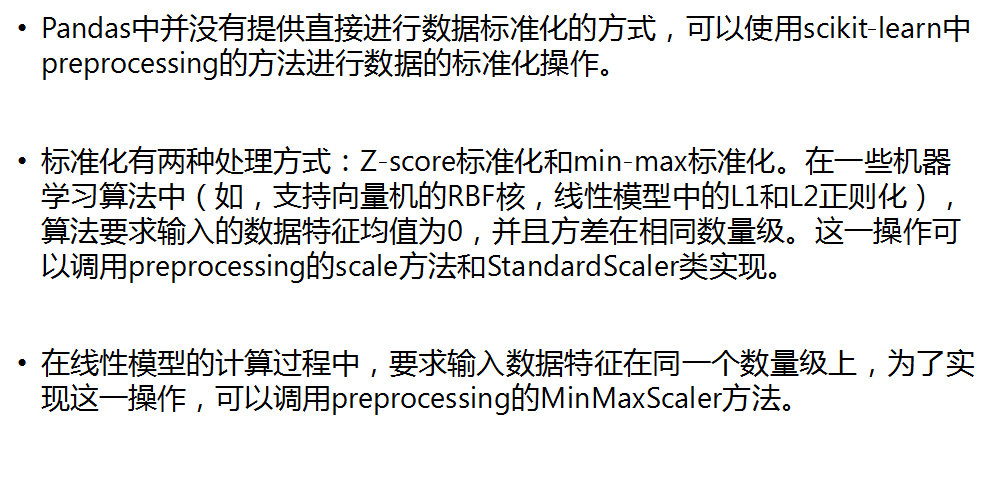
Python 数据标准化 樊伟胜 博客园
标准化的目的与归一化一样,都是为了避免某个特征的重要程度过大或过小。标准化的优点:受异常点的影响较小。 适用于繁杂大数据。demopy(scikitlearn,数据的预处理,标准化,StandardScaler):from sklearnpreprocessing import StandardScaler# 标准化处理std = StandardScaler 文章目录前言一、什么是特征预处理?二、特征预处理常用方法:归一化、标准化1归一化2标准化总结前言提示:这里可以添加本文要记录的大概内容一、什么是特征预处理?sklearn官网的解释:The sklearnpreprocessing package provides several common utility functions and transformer classes to change raw feature vectors into a from sklearnpreprocessing import StandardScaler # 标准化工具 import numpy as np x_np = nparray(15, 1, 2, 2, 0, 0) scaler = StandardScaler() x_train = scalerfit_transform(x_np) print('矩阵初值为:{}'format(x_np)) print('该矩阵的均值为:{}\n 该矩阵的标准差为:{}'format(scalermean_,npsqrt(scalervar_))) print('标准差标准化的矩阵

Scikit Learnで標準化をする時にstandardscalerを使ってみた話 Ensekitt Blog
Scikit Learn之旅 Python机器学习
方法一:最小最大标准化 公式: min指x所在列的最小值,max指x所在列的最大值。 x'指标准化后的x。 代码如下: 注释:①标准化后的数据框d还是数据框格式~ ②数据框下面的rename ()方法可以用于对数据框的列名进行随意更改~采用字典格式进行列名修改 from sklearnpreprocessing import StandardScaler # # 标准化(使特征数据方差为1,均值为0) # 使用sklearn的包 scaler = StandardScaler() scalerfit(data_2) # 使用transfrom必须要用fit语句 trans_data_2 = scalertransform(data_2) # transfrom通过找中心和缩放等实现标准化 fit_trans_data_2 = scalerfit_transform(data_2) # fit_transfrom为先拟合数据,然后转化 import numpy as np from sklearnpreprocessing import StandardScaler scaler = StandardScaler () num_instances, num_time_steps, num_features = train_datashape train_data = npreshape (train_data, shape= (1, num_features)) train_data = scalerfit_transform (train_data) This will reshape the data in a format where each feature is one column and

数据预处理 数据标准化standardscaler Mb5fed71eeb026e的技术博客 51cto博客

机器学习 数值型 数据特征预处理no 2 白红宇的个人博客
Python scikitlearn,数据的预处理,标准化,StandardScaler 发布时间: 标准化的目的与归一化一样,都是为了避免某个特征的重要程度过大或过小。The standard score of a sample x is calculated as 样本x的标准分数计算如下: z = (x u) / s where u is the mean of the training samples or zero if with_mean=False, and s is the standard deviation of the training samples or one if with_std=False 其中u是训练样本的均值,如果with_mean=False,则为0 MinMaxScaler vs StandardScaler – Python Examples In machine learning, MinMaxscaler and StandardScaler are two scaling algorithms for continuous variables The MinMaxscaler is a type of scaler that scales the minimum and maximum values to be 0 and 1 respectively While the StandardScaler scales all values between min and max so that they fall
Python Scikit Learn 数据的预处理 标准化 Standardscaler Houyanhua1的博客 Csdn博客 Python Standardscaler
Sklearn Preprocessing Standardscaler Scikit Learn 1 0 2 Documentation
We can apply the StandardScaler to the Sonar dataset directly to standardize the input variables We will use the default configuration and scale values to subtract the mean to center them on 00 and divide by the standard deviation to give the standard deviation of 10 First, a StandardScaler instance is defined with default hyperparametersThe following are 30 code examples for showing how to use sklearnpreprocessingscale()These examples are extracted from open source projects You can vote up the ones you like or vote down the ones you don't like, and go to the original project 首先定义一个对象: ss = sklearnpreprocessingStandardScaler (copy=True, with_mean=True, with_std=True) 在这里 copy;

数据预处理 数据标准化standardscaler Mb5fed71eeb026e的技术博客 51cto博客
Github Zhouxuanxian Sklearn Preprocessing Minmaxscaler Standardscaler 运用sklearn Preprocessing Minmaxscaler 和sklearn Preprocessing Standardscaler 分别对数据进行归一化和标准化的处理
Standardization using StandardScaler Notebook Data Logs Comments (3) Competition Notebook Ghouls, Goblins, and Ghosts Boo! つまりなにしたの? 今まで前処理のコードはかなり自前で書いてしまうことが多くて、Scikitlearnの機能を使えていないな〜と思ったので、 StandardScaler見たいなシンプルな機能から使ってみることにした。 基本的にはPandasのDataFrameで定義されたデータセットに対して前処理を実施していく流れLogisticregressionusingpythonsklearnnumpymnisthandwritingrecognitionmatplotliba6b31e2b166a )。 我们学到的一件事是,你可以通过改变优化算法来加速机器学习算法的拟合。 加速机器学习算法的一种更常见的方法是使用主成分分析 Principal Component Analysis (PCA)。 如果你
机器学习基础一文带你用做特征工程 新闻时间

机器学习 十五 预处理和缩放 Standardscaler Robustscaler Minmaxscalar Normalizer Codeantenna
如果您的时间序列呈现上升趋势或下降趋势,那么估计这些预期值可能会很困难,并且标准化法可能不是用于解决问题的最佳方法。 一个标准化的值如下: y = (x min) / (max min) 最小值和最大值与规范化的值 x 有关。 例如,对于温度数据,我们可以猜测最小和查询Maven配置文件位置,并添加阿里镜像提速 感觉近段时间以来,maven官方repo的下载速度越来越快了,不知道是怎么一回事,哈哈。 不过相比国内镜像,还是慢很多。 Step1: 查询使用的配置文件位置 maven的配置文件是在settingxml文件中定义的,对其修改前要使用Python进行数据标准化 读取数据 首先,加载pandas和numpy库,读取数据。 import pandas as pd i 王吉林 阅读 453 评论 0 赞 0 18最新Python数据分析实战教程视频 python数据分析班视频 Python数据分析 系列一:《python数据分析基础与实践》 章节1Python概况 课时2Python
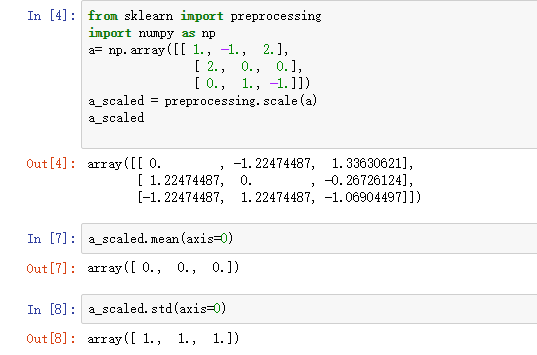
Python中数据标准化 Qian Fighting的博客 Csdn博客 Python 标准化

机器学习 特征工程 数据的标准化 Z Score Maxmin Maxabs Robustscaler Normalizer Huangguohui 123的博客 程序员宅基地 程序员宅基地
在python上数据归一化后怎样还原呢? 例如: scaler = sklearnpreprocessingStandardScaler()fit(train) test_S = scalertransform(test) test1 = scalerinverse_transform(test_S) 这时 test1 应该和 test 是一样的。It is unclear or not useful Bookmark this question Show activity on this post I have following pipeline estimators = estimatorsappend ( ('standardize', StandardScaler ())) prepare_data = Pipeline (estimators) Originally, the data looks like After applying the estimator/ StandardScaler () 使用sklearn进行对数据标准化、归一化以及将数据还原的方法 今天小编就为大家分享一篇使用sklearn进行对数据标准化、归一化以及将数据还原的方法,具有很好的参考价值,希望对大家有所帮助。 一起跟随小编过来看看吧 在对模型训练时,为了让模型尽快

Scikit Learn使い方まとめ 機械学習 Qiita

使用sklearn进行数据预处理 菜鸟学院
Python数据预处理(sklearnpreprocessing)—归一化(MinMaxScaler),标准化(StandardScaler),正则化(Normalizer, normalize) 关于数据预处理的几个概念 归一化 (Normalization): Edit 2 Came across the sklearnpandas package It's focused on making scikitlearn easier to use with pandas sklearnpandas is especially useful when you need to apply more than one type of transformation to column subsets of the DataFrame, a more common scenarioIt's documented, but this is how you'd achieve the transformation we just performedStandardScaler It transforms the data in such a manner that it has mean as 0 and standard deviation as 1In short, it standardizes the dataStandardization is useful for data which has negative values It arranges the data in a standard normal distribution It is more useful in classification than regressionYou can read this blog of mine Normalizer It squeezes the data between 0 and 1

真的明白sklearn Preprocessing中的scale和standardscaler两种标准化方式的区别吗 爱代码爱编程

机器学习入门 11 特征工程 特征预处理 归一化 标准化 每日头条
classpreprocessingStandardScaler(copy=True, with_mean=True,with_std=True): 今天是读《python数据分析基础》的第17天,读书笔记的内容为变量的标准化。 在进行 在建模的时候,会遇到不同的自变量之间的量纲差距很大的情况,如输入变量Standardization using StandardScaler Python Ghouls, Goblins, and Ghosts Boo!Standardize features by removing the mean and scaling to unit variance The standard score of a sample x is calculated as z = (x u) / s where u is the mean of the training samples or zero if with_mean=False , and s is the standard deviation of the training samples or one if with_std=False Centering and scaling happen independently on each feature by computing the relevant
2

使用sklearn进行数据预处理 宁哥的小站
5 Feature Normalization — Data Science 01 documentation 5 Feature Normalization ¶ Normalisation is another important concept needed to change all features to the same scale This allows for faster convergence on learning, and more uniform influence for all weights More on sklearn website Treebased models is not dependent on scalingSklearnpreprocessingscale¶ sklearnpreprocessing scale (X, *, axis = 0, with_mean = True, with_std = True, copy = True) source ¶ Standardize a dataset along any axis Center to the mean and component wise scale to unit variance Read more in the User Guide Parameters 1) 변수들의 단위 차이로 인해 숫자의 스케일이 크게 달라지는 경우 이 경우에는 스케일링 (scaling)으로 해결한다 2) 다중 공선성 즉, 상관관계가 큰 독립 변수들이 있는 경우, 이 경우에는 변수 선택이나 PCA를 사용한 차원 축소 등으로 해결한다 그리고 다음과
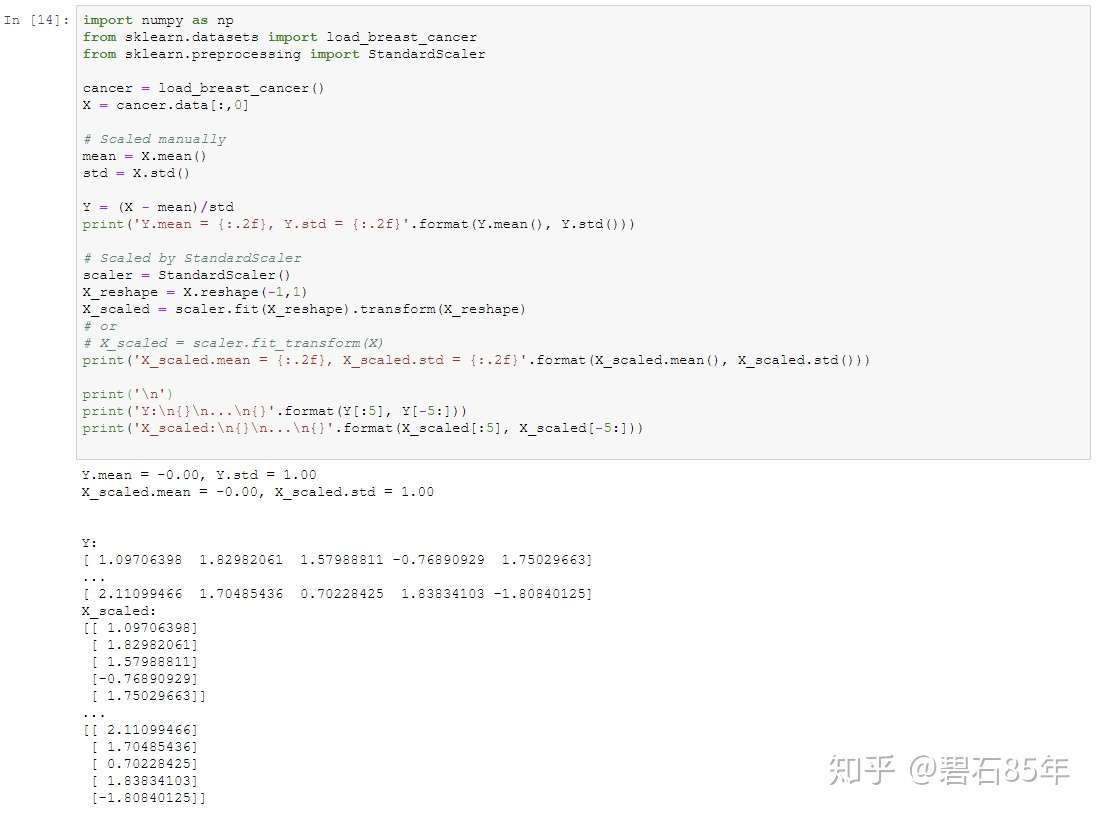
Standardscaler原理 知乎

Standardscaler Taustation
Standardscaler原理 知乎

Python数据预处理 彻底理解标准化和归一化 哔哩哔哩
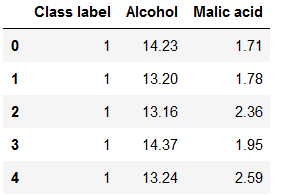
Python实现数据预处理 特征标准化与归一化 航行学园

Scikit Learn 备忘单 Python 机器学习 博客

Sklearn学习笔记 2 代码先锋网

Python之fit Transform Fit Transform区别和作用详解 Liujingwei8610的专栏 程序员资料 程序员资料

Sklearn特征预处理 归一化minmaxscaler 标准化standardscaler 代码先锋网
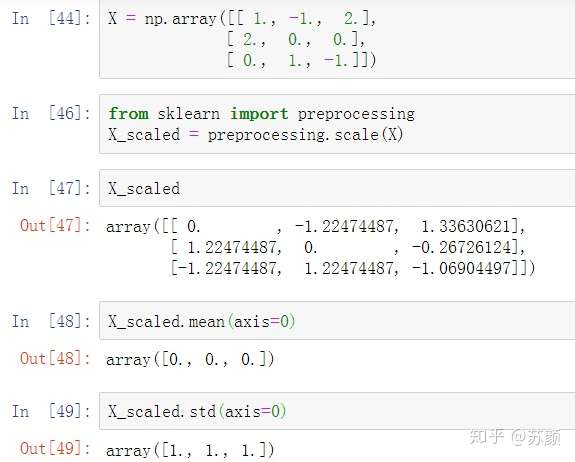
Python Standardscaler数据标准化 知乎
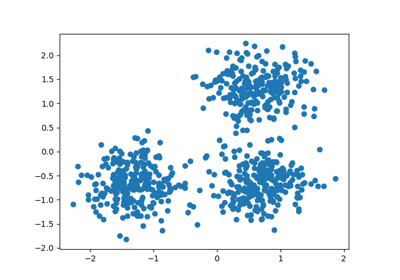
Sklearn Preprocessing Standardscaler Scikit Learn 1 0 2 Documentation

详解python特征工程算法 编程宝库

数据标准化与规范化与稳健缩放器 Python 22

Sklearn中的数据预处理 Good 标准化归一化在何时使用 Bonelee 博客园
数据归一化和其在sklearn 中的处理 开发者头条

如何将numpy数组标准化到一定范围内 Python 22

Sklearn Standardscaler で標準化の効果を確かめる Python コード7区

Scikit Learnで標準化をする時にstandardscalerを使ってみた話 Ensekitt Blog

Sklearn中的数据预处理 Good 标准化归一化在何时使用 Mb5fed71eeb026e的技术博客 51cto博客
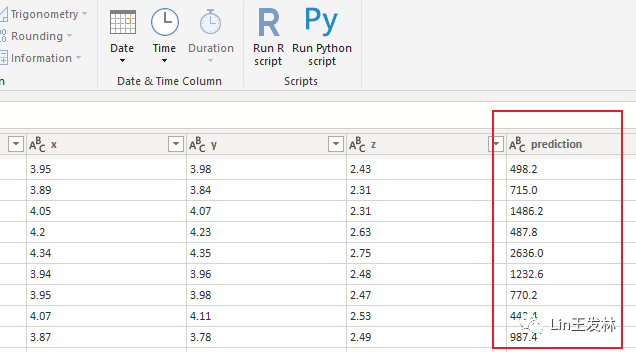
Powerbi使用python进行数据预处理 机器学习 Knn模型 墨天轮

Python数据预处理之数据标准化的几种处理方式 灰信网 软件开发博客聚合

使用sklearn进行对数据标准化 归一化以及将数据还原使用sklearn进行对数据标准化 归一化以及将数据还原的方法 It技术

数据标准化处理 何国庆的博客 程序员宅基地 程序员宅基地
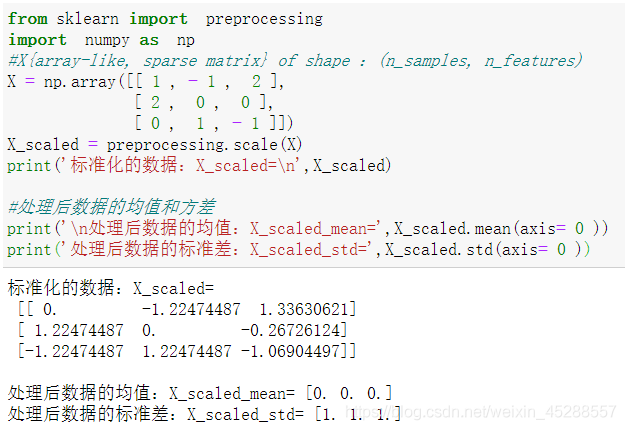
数据预处理之 一 标准化 去均值和方差按比例缩放 佐佑思维 Mdeditor

机器学习中的数据预处理 7个简单的步骤 科技 大国新闻网

Sklearn Preprocessing里的normalizer Standardscaler Minmaxscaler 啊哟喂gzxb的博客 Csdn博客

Python成神之路 机器学习 4 特征预处理

Sklearn中standardscaler Codeantenna
数据归一化和其在sklearn 中的处理 开发者头条

机器学习之归一化和标准化 编程猎人

Sklearn中的数据预处理 Good 标准化归一化在何时使用 Mb5fed71eeb026e的技术博客 51cto博客

数据预处理 Zdaiot

Numpy数组 标准化数据 编程猎人
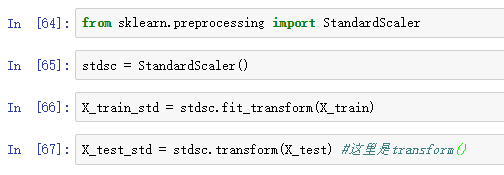
统一特征取值范围 Python机器学习
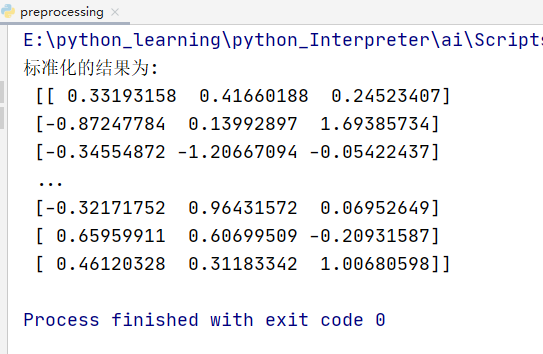
机器学习入门 特征工程 特征预处理 Littlemelon 博客园

在python虚拟环境下对鸢尾花数据集进行svm线性分类 在python虚拟环境下对鸢尾花数据集进行svm线性分类 Samuel个人博客

Scikit Learn数据预处理 对特征进行归一化和标准化 一页孤沙的博客 程序员资料 程序员资料

谁能解释我standardscaler Python 22
机器学习 数据标准化的方法 知乎

原 关于使用sklearn进行数据预处理 归一化 标准化 正则化 Chaosimple 博客园

机器学习 Svm之python实现数据样本标准化和归一化 Python Ai Fans的博客 程序员资料 Svm数据标准化 程序员资料

Skearn预处理standardscaler出现valueerror 的错误 Llh 1178的博客 Csdn博客 Standardscaler报错

Day 5 資料清理 前處理 It 邦幫忙 一起幫忙解決難題 拯救it 人的一天

数据预处理 Sklearn Preprocessing Onehotencoder 标准化 正则化 缺失值 Standardscaler Fit Transform Berlin的博客 程序员宝宝 程序员宝宝

Api解析 特征工程标准化standardscaler 函数 西安人走哪都要吃泡馍的博客 Csdn博客 Standardscaler函数

Sklearn Standardscaler で標準化の効果を確かめる Python コード7区

吴裕雄python 机器学习 数据预处理标准化standardscaler模型 Mb5fdb09f39fed1的技术博客 51cto博客

Python成神之路 Sklearn之数据预处理 Standardscaler
Python 数据预处理 归一化和离散化 Minmaxscaler Standardscaler Cut Qcut 皿 っhiahiahia 的博客 程序员资料 程序员资料

数据预处理 使用pandas 进行数值型数据的标准化归一化离散化二值化 机器快点学习 博客园

Sklearn中的fit与fit Transform Codeantenna

小萌五分钟 机器学习 数据预处理之特征缩放 归一化 Normalization 标准化 Standardization 哔哩哔哩 Bilibili

Python数据分析中使用pandas进行预处理的标准化数据 Winda Shi的博客 程序员宝宝 程序员宝宝
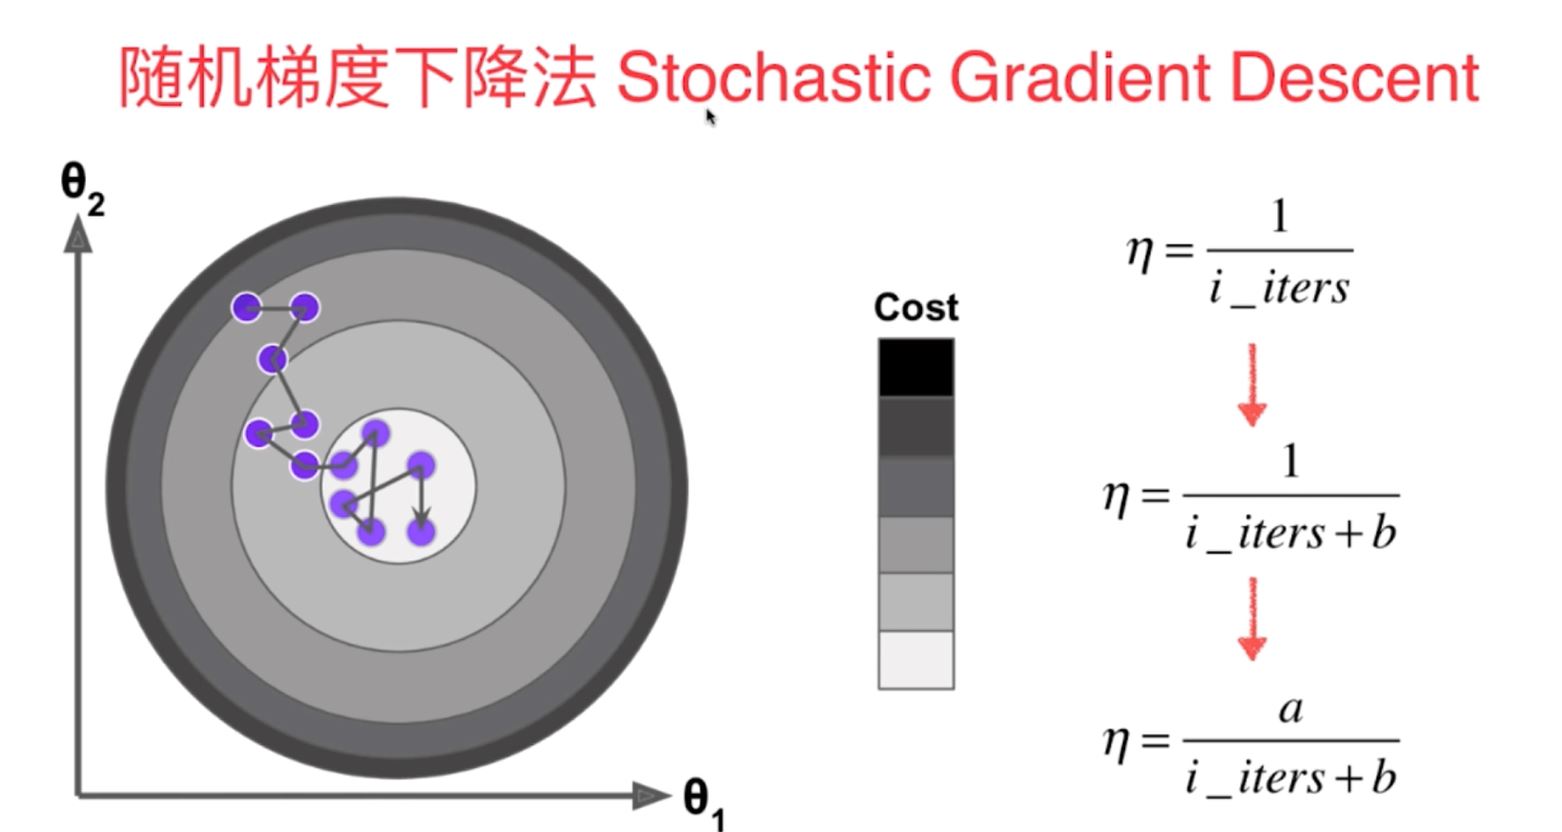
Sklearn中实现随机梯度下降法 多元线性回归 白红宇的个人博客

数据标准化处理方法 数据标准化方法 爱代码爱编程

代码片段 基于6种监督学习 逻辑回归 决策树 随机森林 Svm 朴素贝叶斯 神经网络 的毒蘑菇分类

机器学习中归一化与标准化 Codeantenna

谁能解释我standardscaler Python 22
译 对比归一化和标准化 量化分析 掘金

Python 数据标准化 Mb5fe559b5073e8的技术博客 51cto博客

利用sklearn Preprocessing Standardscaler进行数据标准化 Cyj的博客 程序员宅基地 程序员宅基地

Python 数据预处理时的标准化standardization 归一化normalization 哇哇咔咔mz Y的博客 Csdn博客 Python Standardization

Sklearn Preprocessing Standardscaler采用的是哪种标准化的方法 Sofasofa
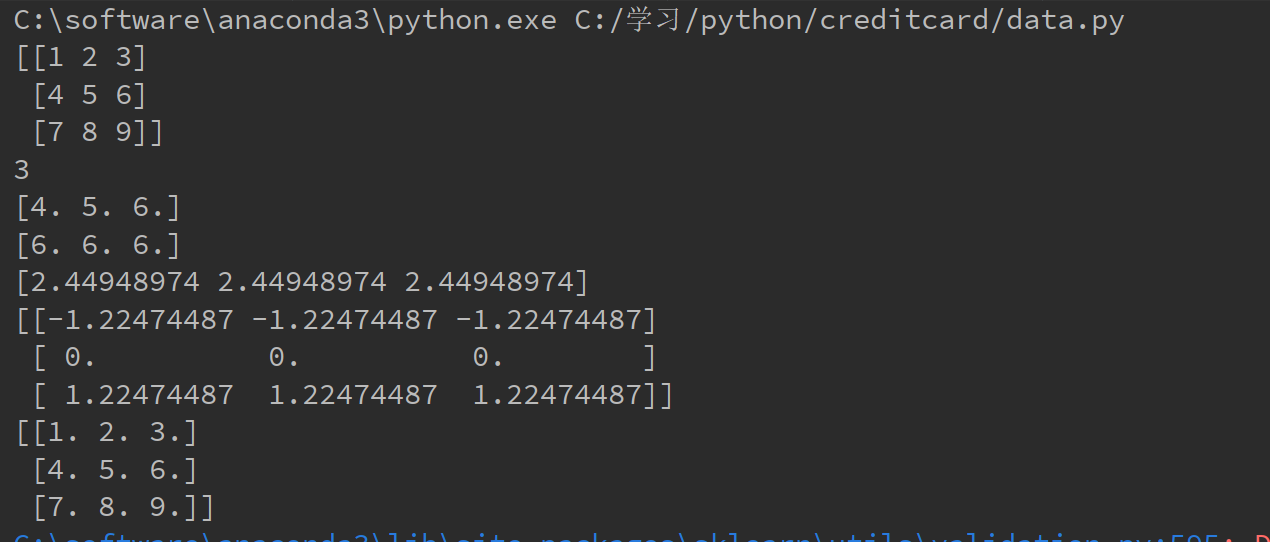
Sklearn Preprocessing Standardscaler数据标准化 地球上最后一个直男 博客园

机器学习 07 Sklearn中的数据预处理 简书

真的明白sklearn Preprocessing中的scale和standardscaler两种标准化方式的区别吗 爱代码爱编程

谁能解释一下standardscaler 经验摘录
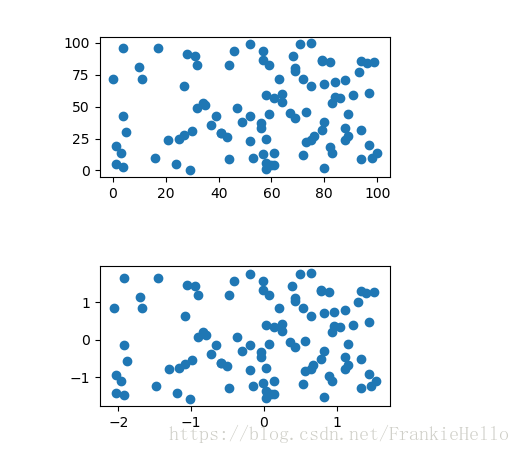
使用sklearn进行对数据标准化 归一化以及将数据还原 敲代码的quant的博客 Csdn博客 Sklearn 归一化

Python数据标准化是什么 Python学习网

Sklearn中的数据预处理 Good 标准化归一化在何时使用 Mb5fed71eeb026e的技术博客 51cto博客
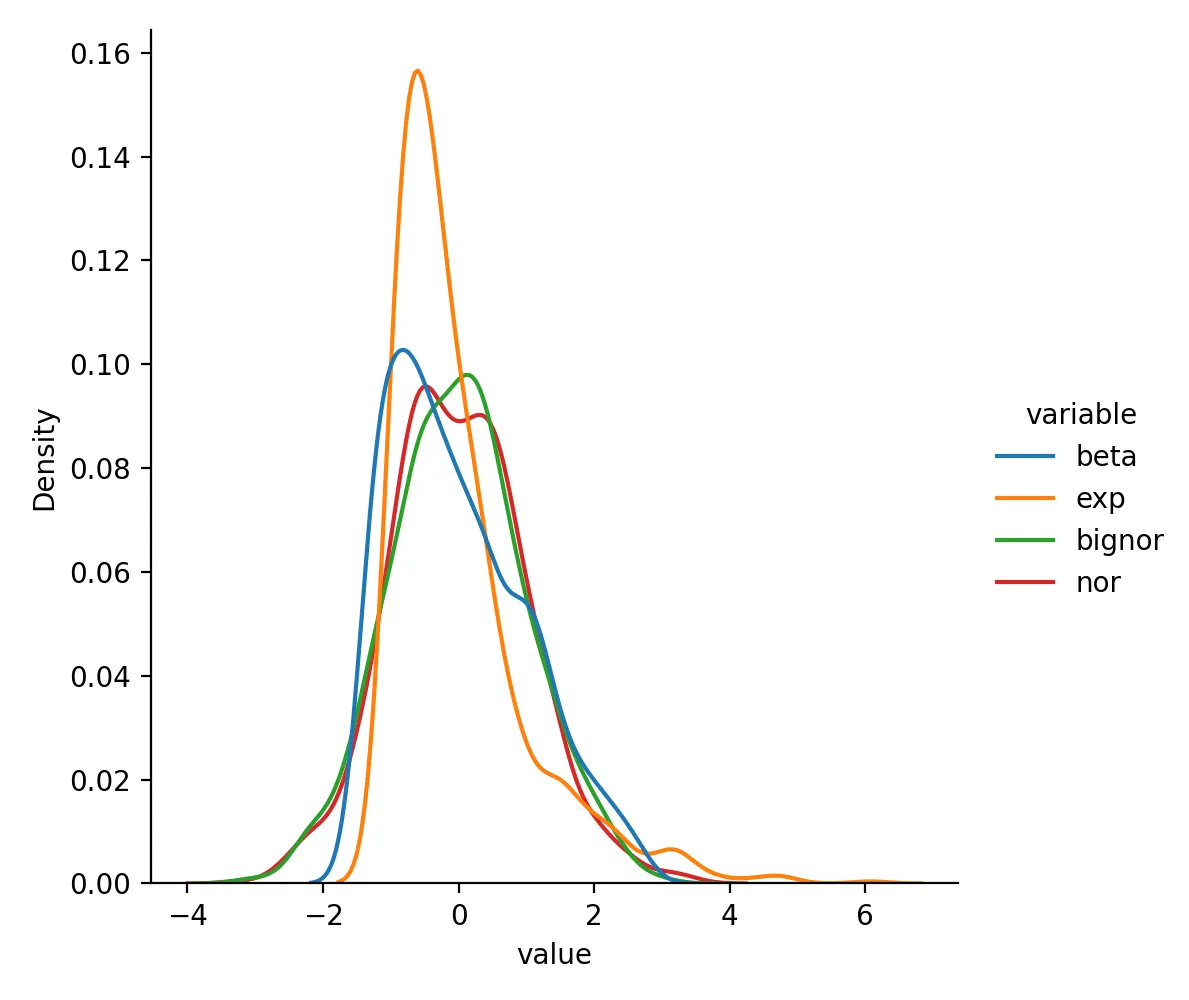
预处理方法scale Standardize Normalize的选择 春江暮客
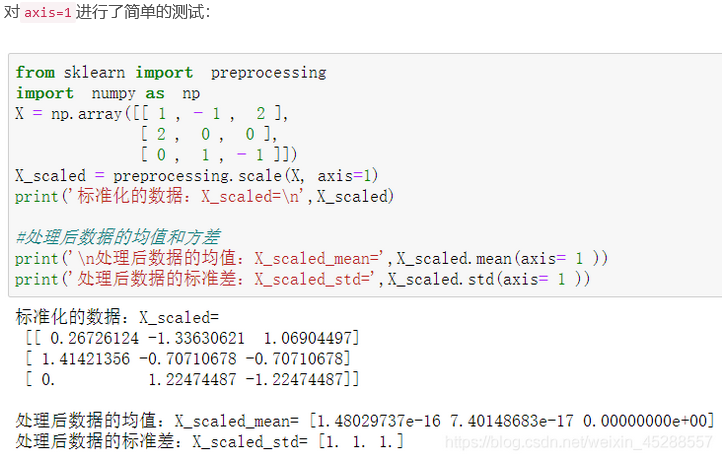
数据预处理之 一 标准化 去均值和方差按比例缩放 佐佑思维 Mdeditor
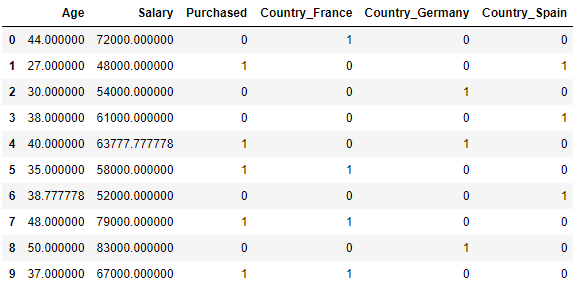
机器学习基础 Python数据预处理 彻底理解标准化和归一化 技术圈

长文详解python数据预处理 快收藏 Scaling
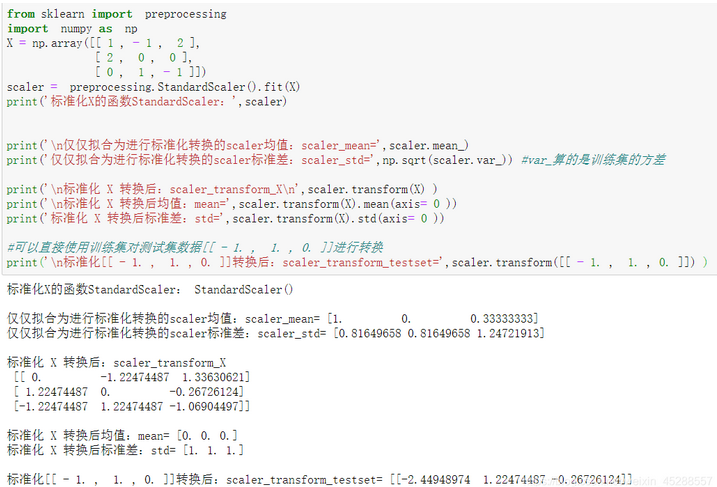
数据预处理之 一 标准化 去均值和方差按比例缩放 佐佑思维 Mdeditor

机器学习算法基础 基础机器学习课程 第二天 拜师资源博客

Sklearn三种数据标准化方法的对比 Standardscaler Minmaxscaler Robustscaler Smilecoc S Blog
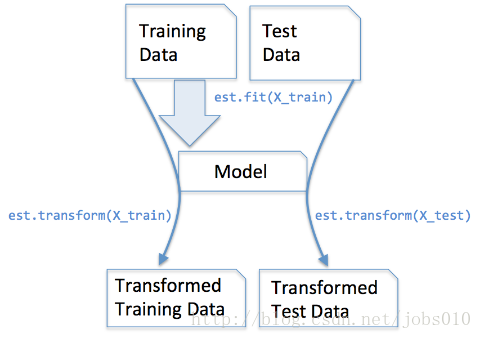
Sklearn 数据预处理函数fit Transform和fit Transform的区别 粘世强的博客 Nsq Blog

Kaggle 指南 三 数据预处理 简书

机器学习 数据特征预处理 归一化以及标准化对比 34丶的博客 程序员信息网 数据预处理归一化和标准化哪个好 程序员信息网


コメント
コメントを投稿